Character Recognition

Dear all,
Currently I am working on character recognition in a natural scene image. As it is an academic project, so following assumptions are fixed for an input image.

1- Font Family & size is fixed.

2- Only color can vary.

While the characters are embedded inside of some random natural image. So we need to localize characters in an image first followed by its recognition.
I was planning to use co-relation between the template and test image but it works fine only for binary images. For an RGB image i did segmentation but after that co-relation is not working. So please can any one share a simple mechanism to implement this project?

Regards

You should post sample images and some initial CODE that you wrote.

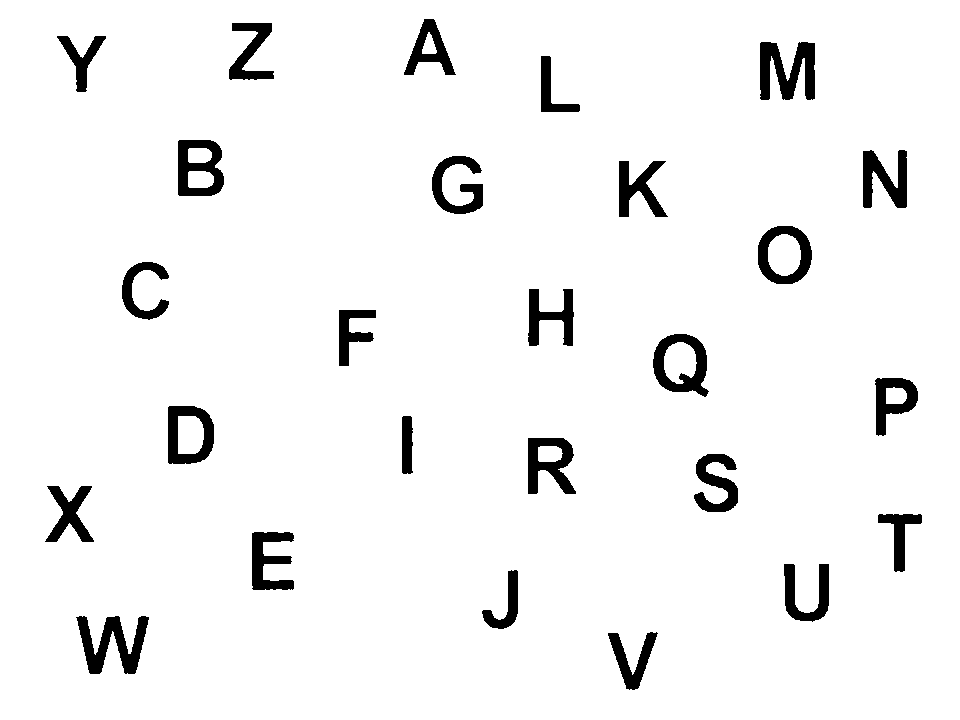
This is the image, what I want to do is to extract letters from this image followed by recognition. Well code is simple correlation between a template image (containing a letter to detect) and test image (containing all alphabets – binary image). So for binary version this approach is perfectly working but as soon as I implement same strategy to this image it doesn’t work. So kindly share your thoughts on it, is there any other better way to do it. I want to keep things simple as i have to implement it in java without using any external lib.

Hello Muhammad,

from your post I could not find out whether the characters have a fixed specific color or not. If they do have a specific color, then a solution might be (let img be your original image):

red = {.93, .1, .15};
letterImg = ImageApply[If[EuclideanDistance[#, red] < .2, 0, 1] &, img]

giving:

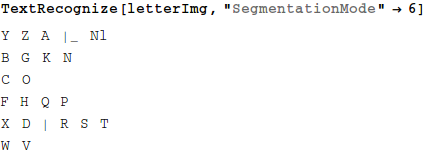
which can be treated with TextRecognize. If one uses the documentation the result is frustrating: It simply does not work! Only when choosing a non-documented (!) option, things appear to work a bit:

I myself learned about this valuable option (and more) from another interesting post of Marco Thiel (thanks Marco!). I do not understand why those details are undocumented. (In case it is documented meanwhile (v10.3.1), then just ignore my last remark.)

Regards – Henrik
[1]: http://community.wolfram.com//c/portal/getImageAttachment?filename=letterImg.png&userId=32203
[2]: http://community.wolfram.com//c/portal/getImageAttachment?filename=TextRecognize.png&userId=32203
[3]: TextRecognize giving inconsistent performance

Hello Henrik,

Thanks for your response. I already did segmentation based on character color but the issue is color is not fixed. So right now I don’t know which characteristics shall i use for alphabet segmentation. If you know other method kindly share it.

Regards

Hello Muhammad,

I am afraid I did not read you first post careful enough, sorry! OK, here comes another try:

Let img be your original image, then I construct and apply a sort of an “edge mask”:

img1 = ColorQuantize[img, 15];
edgeMask = ColorNegate@Dilation[EdgeDetect[img1], 2];
img2 = ImageMultiply[img1, edgeMask]

which gives:

Having done this preparation we can convince ourself that MorphologicalComponents does the trick:

(mc = MorphologicalComponents[img2]) // Colorize

This results in more than 1000 components, which are represented in their own part of the image (using automated crop).
Since the font size is fixed, one can have a rough idea about the expected size of those images which contain letters:

{min, max} = MinMax[mc]
(* Out:  {0, 1029} *)

levelImages = ParallelTable[{n, i = Function[{level}, ImageCrop@Image@Map[If[# == level, 0, 1] &, mc, {2}]][n], 
    ImageDimensions[i]}, {n, min, max}];

letterCandidats = Select[levelImages, With[{xdim = #[[3, 1]], ydim = #[[3, 2]]}, (40 < xdim < 70) && (40 < ydim < 70)] &];

{#1, #2, TextRecognize[#2, "SegmentationMode" -> 6]} & @@@ letterCandidats

The result then looks like:

Maybe this might be a way for an approach . Regards – Henrik

Hi Henrik,
Thanks for your feedback. I will give it a try.

Regards